Ideas / failures / validation
Blog
Longer accounts of how a result failed, what the failure exposed, and which checks were worth keeping.
-
Two agents, and no way to tell if either one workedwhy I helped start a benchmark instead of building a third
Part 3. I wrote the agents and I wrote the checks that graded them — which is a self-assessment, not a test. Why that led to helping start a benchmark, and the honest state of it.
Read the post -
Building an AI agent that can’t fake drug-target evidencefrom a metabolite in blood, through the gene behind it, to whether it is worth a drug
Part 2. LLMs hallucinate. The same agent rebuilt to start from a molecule in blood: it names the gene behind the molecule, refuses a question it cannot read, and computes its verdict instead of letting a model write one.
Read the post -
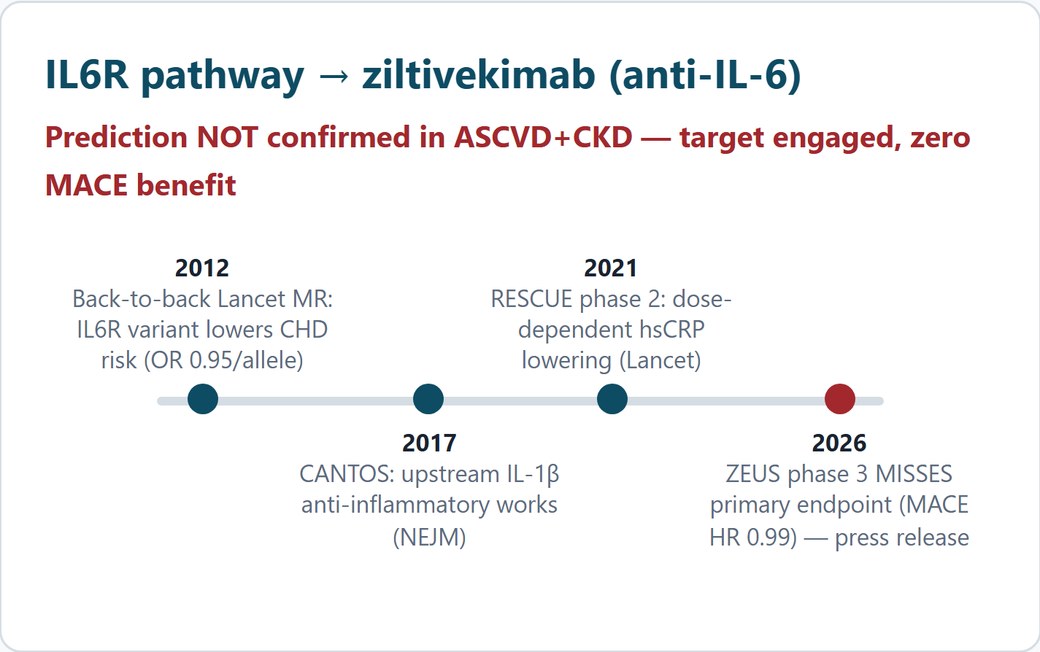
Building an AI agent that can’t fake drug-target evidencefrom a protein to whether it is worth a drug
Part 1. LLMs hallucinate, and gathering the evidence behind a result is still done by hand. An agent for biomedicine that only prints what its sources returned.
Read the post